This project started with a problem that sounds simple until you try to solve it at scale: how do you turn uneven faculty records into useful expert profiles without making people sound more specific, current, or authoritative than the evidence supports?
The first proof of concept combined structured eligibility rules with model-assisted writing. One part of the system decided whether the available evidence was strong enough to support a profile. The other turned that evidence into a short, readable summary and a focused set of keywords. Separating those jobs was important. It kept the model from deciding that polished language was proof of expertise.
That early version worked well enough to prove the idea, but it also exposed the harder problem. A system can produce clean copy and still make weak editorial decisions. Publication titles can look coherent while providing too little context. Course lists can suggest a field without establishing an expert-facing domain. A fluent summary can quietly smooth over conflicts or missing information that should have stopped the process.
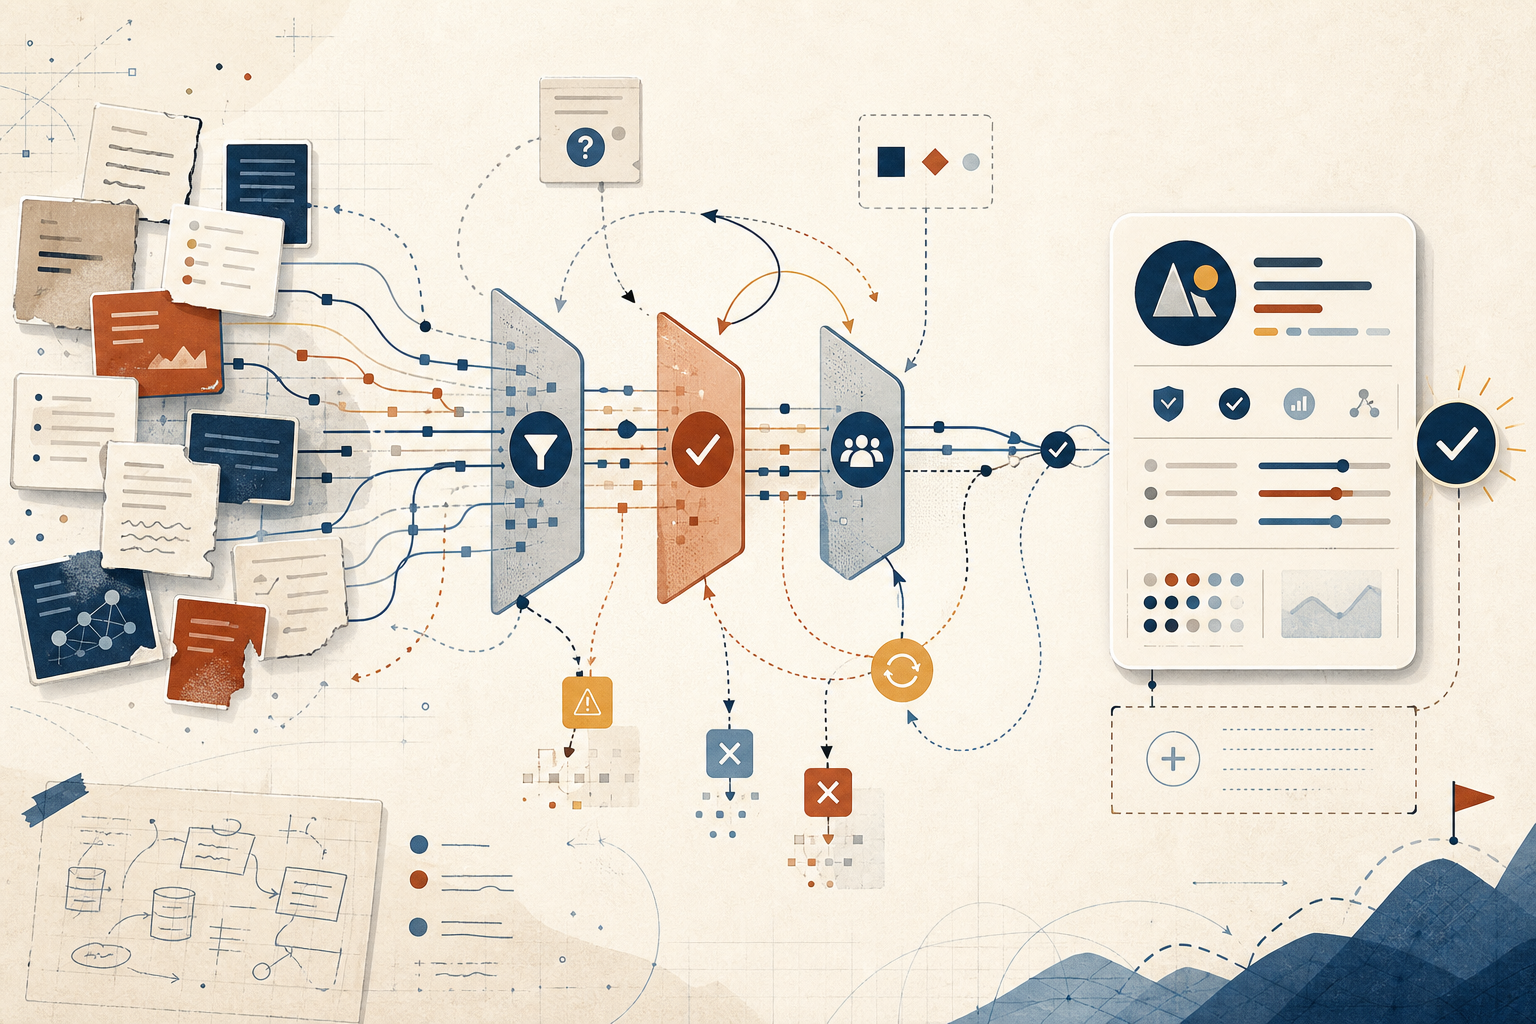
The system now uses a more deliberate evidence order. Specific research interests come first, followed by substantive biography or experience that establishes a coherent domain. Teaching interests can support that picture, while course records are confirmational. Publications can corroborate or refine a domain established by stronger sources, but they do not establish eligibility on their own.
The current prototype pulls scholarly evidence from Digital Measures and uses Workfolio to confirm current directory context. Every record moves into one of three lanes: publishable, manual review, or do not include. That middle lane matters. Some profiles contain potentially useful evidence but also have a conflict, ambiguity, or unsupported leap that automation should not resolve by itself.
The writing process has also grown beyond a single generation step. A sourced challenger is drafted, critiqued without being rewritten on the spot, revised against the evidence, and compared with strong reference profiles. If reviewed copy already exists, the challenger has to be materially better before it can replace the incumbent. A source refresh does not silently overwrite accepted language; meaningful changes return to review.
That approach has caught several failure modes that were easy to miss in the original proof of concept: generic fallback blurbs, publication-count filler, malformed source text, damaged acronym casing, noisy keywords, and summaries that sounded convincing without telling a reader what the person could credibly discuss. It has also reinforced a less technical lesson: better automation often comes from giving a system more ways to stop.
This is still actively in development and only barely beyond the proof-of-concept phase. The evidence rules, review states, regression checks, and public rendering path are much stronger than they were at the start, but the work is not finished. The system still needs careful human review, clearer handling of edge cases, and continued testing to make sure a future improvement in fluency does not become a regression in judgment.
That is what keeps the project interesting to me. The goal is not to automate confidence or maximize the number of profiles the system can publish. It is to build a process that can use automation without hiding uncertainty, protect decisions that have already been reviewed, and produce public writing that can be defended.